For a decade, the Silicon Valley mantra “Move Fast and Break Things” dictated global engineering culture. It was an exciting philosophy for building consumer photo-sharing apps in 2012.
In 2026, applying that philosophy to B2B SaaS, fintech, or logistics software is professional negligence.
When an enterprise logistics platform goes offline for 15 minutes due to a rushed deployment, it does not just annoy users; it halts global supply chains and burns hundreds of thousands of dollars. The most elite engineering teams do not move fast by breaking things. They move fast because their software development processes are so rigorously structured that breaking things in production becomes nearly mathematically impossible.
Google Cloud’s 2024 State of DevOps (DORA) report, the longest-running research program on software delivery performance, found that elite-performing engineering teams deploy code on demand — multiple times per day — with a change lead time under one day and a change failure rate around 5%. Teams in the “low” performer cluster, by contrast, take between one month and six months to ship a single change and can take up to a month to recover when a deployment fails. That gap is not incremental; it is the difference between shipping the same week a decision is made and shipping the following quarter.
If you are a CTO struggling with fragile codebases, here is the autopsy of the modern software development cycle, and the exact processes required to scale safely.
1. The Death of “Agile Theater”
Most companies claim they use Agile. In reality, they are practicing “Agile Theater.” They still write 100-page requirement documents, but they happen to have a 15-minute daily meeting they call a “Standup.” This results in the worst of both worlds: the rigidity of Waterfall without the predictability.
The Professional Process (Scrum / Kanban Mastery):
- Strict Cycle Limits: If a feature cannot be built, tested, and deployed within a 2-week Sprint, it is not a feature; it is an Epic. It must be broken down further.
- The Definition of Ready (DoR): Developers should never start coding based on a vague Jira ticket. The DoR dictates that a ticket must have strict Acceptance Criteria, a finalized Figma UI, and an agreed-upon API payload before it enters the Sprint backlog.
2. Shift-Left Security and Quality Assurance
In amateur teams, QA is the final step. A developer writes the code, throws it over the wall to a manual QA tester, and waits for a spreadsheet of bugs. This process is inherently slow and antagonistic.
Elite teams use “Shift-Left” processes. Quality is tested as early in the cycle as possible.
- Test-Driven Development (TDD): Developers write the automated unit tests before they write the business logic.
- Static Application Security Testing (SAST): Before code is even merged, tools like SonarQube automatically scan the Git branch for hardcoded credentials, infinite loops, and known CVE vulnerabilities.
- Peer Review as an Architectural Gate: Code is never merged without approval from a Senior Architect. This is not just checking for typos; it is ensuring the code aligns with the overall system architecture.
3. The CI/CD Assembly Line (Zero-Touch Deployment)
If a developer needs to manually SSH into a Linux server or drag-and-drop an FTP folder to deploy code, your process is archaic. Manual deployment guarantees human error.
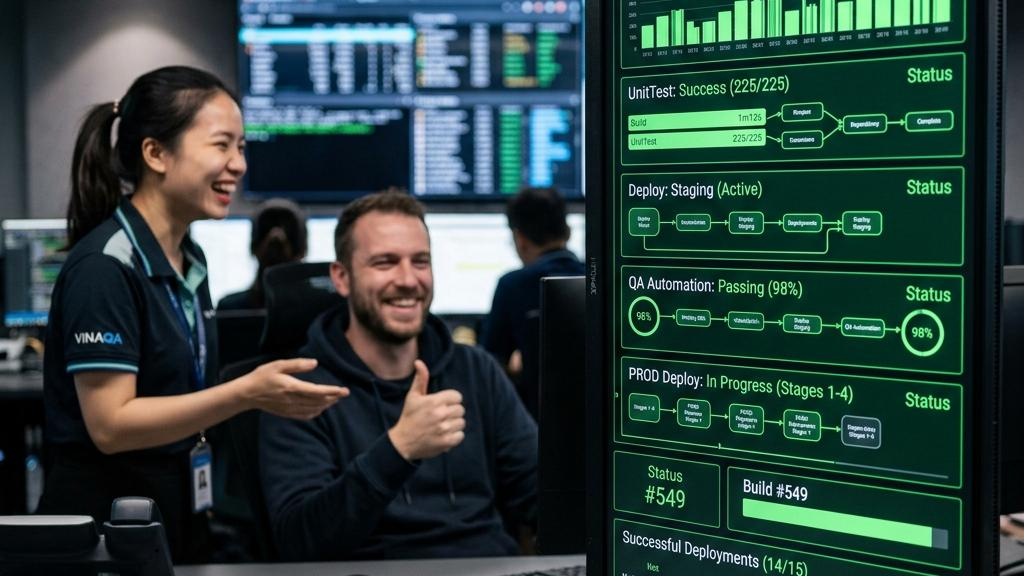
Continuous Integration / Continuous Deployment (CI/CD): The modern custom software development lifecycle relies on absolute automation.
- The Merge Trigger: Code is merged into the
mainbranch. - The Pipeline: GitHub Actions automatically provisions an isolated container, installs dependencies, and runs the entire suite of 5,000 unit tests. If one test fails, the deployment halts instantly.
- The Deployment: If tests pass, ArgoCD (using GitOps principles) automatically synchronizes the live Kubernetes cluster with the new code state.
No human touches the production server.
Progressive Delivery: Feature Flags, Canary Releases, and the Blameless Postmortem
Even with a flawless CI/CD pipeline, “deploy” and “release” are not the same event. Elite teams deliberately separate them, because the moment code reaches production is not the moment it should reach every user.
Feature Flags as a Circuit Breaker: Instead of shipping a new checkout flow to 100% of traffic simultaneously, the code is wrapped in a feature flag (using a platform like LaunchDarkly or an open-source equivalent). The new logic is deployed to production dark, invisible to real users, and then progressively exposed.
- Canary Releases: The flag is enabled for 1% of traffic, typically internal staff or a small cohort of low-risk accounts. Error rates, latency, and conversion metrics are monitored in real time.
- Progressive Rollout: If the canary cohort shows no regression after a fixed observation window, exposure widens to 10%, then 50%, then 100%. If a single metric degrades at any stage, the flag is flipped off instantly, no redeploy required, and the rollout halts without a single user noticing.
This decouples “shipping code” from “risk.” A bug can sit dormant in production for weeks behind a disabled flag with zero blast radius, waiting for the business to decide when to expose it.
The Blameless Postmortem: Mature processes assume incidents will still happen despite every safeguard. What separates elite engineering organizations from amateur ones is not the absence of failure, but the discipline of the response.
- The 5-Whys Root Cause Analysis: After any production incident, the team documents a timeline and asks “why” repeatedly until it reaches the systemic root cause, not the individual who wrote the code.
- No Names, Only Systems: A blameless postmortem never states “Developer X pushed a bad migration.” It states “The pipeline allowed an unreviewed schema migration to reach production because the DoR did not require a rollback script.” This distinction matters enormously: blame-driven cultures cause engineers to hide mistakes; blameless cultures surface them immediately, which is the only way an organization actually gets safer over time.
- Action Items with Owners and Deadlines: Every postmortem produces a small number of concrete engineering changes (e.g., “add a pre-migration dry-run step to the pipeline”), each assigned an owner and a due date, tracked to closure like any other Sprint ticket.
Without this discipline, the same category of incident recurs every few months, and the organization never learns. With it, each failure permanently hardens the pipeline against that specific class of error.
The Metric That Ties It Together: MTTR Mature engineering organizations stop measuring their process purely by how rarely things break, and start measuring Mean Time to Recovery (MTTR): the average time between an incident starting and the system returning to a healthy state. This single metric is the honest scoreboard for feature flags, canary releases, and blameless postmortems combined.
- A team with instant flag rollback and a rehearsed incident process can recover from a bad release in under 5 minutes.
- A team without these processes, relying on a full manual redeploy or a frantic hotfix, often takes 2 to 4 hours to recover, during which the business is actively losing revenue or trust. DORA research consistently shows that elite teams are not defined by never failing; they are defined by an MTTR measured in minutes, not hours. Tracking MTTR as a first-class Sprint metric, alongside velocity and defect count, is what turns “we had an incident” from a crisis into a routine, recoverable event. It also gives a CTO an objective, board-reportable number to defend engineering investment with, rather than a vague assurance that “the team is being careful.”
The DORA Four Keys: Benchmarking Your Process Against the Industry
Every practice described above — Shift-Left QA, CI/CD, feature flags, blameless postmortems — exists to move a team’s numbers on one specific, well-established scorecard: the DORA Four Keys, developed by the DevOps Research and Assessment team (now part of Google Cloud) from over a decade of research across tens of thousands of engineering teams. Rather than asking “does this team feel productive,” the Four Keys measure throughput and stability directly, and the 2024 State of DevOps report groups organizations into four performance clusters based on where they land:
Why this table matters more than any single process on its own: the Four Keys are explicitly a balanced scorecard. A team that deploys constantly but has a 50% change failure rate is not elite, it is reckless. A team with a 2% failure rate that ships once a quarter is not elite either, it is slow. The processes described in this article — the Definition of Ready, SAST scanning, feature-flagged progressive rollout, and blameless postmortems — are precisely the mechanisms that let a team move deployment frequency up and change failure rate down simultaneously, rather than trading one for the other. Historically, DORA’s research has found elite performers deploying roughly two orders of magnitude more frequently than low performers, with dramatically shorter lead times and faster recovery — the compounding effect of disciplined process, not raw engineering headcount.
How to use this table internally: Most engineering leaders have never measured all four metrics simultaneously; they track velocity (story points) or uptime, rarely both throughput and stability together. Start by instrumenting deployment frequency and change failure rate directly from your CI/CD pipeline metadata — both are mechanically derivable from deploy logs and incident tickets, requiring no survey or subjective self-assessment. Once a team can see its own row in this table, “we should ship faster” stops being a vague aspiration and becomes a specific, trackable engineering target.
The “Hub-and-Spoke” Process at Manifera
Designing these processes is difficult. Executing them consistently with a remote team is where most companies fail.
This is why Manifera’s offshore software development model is structured around Dutch process governance. We do not just supply coders; our European Hub enforces the strict Definition of Ready, the CI/CD pipelines, and the Shift-Left QA methodologies. Our engineering centers in Vietnam execute within this unyielding framework.
This hybrid process allows our clients to achieve high-velocity feature releases without ever sacrificing enterprise stability.
Stop breaking things. Start engineering systems.
FAQs
What is “Agile Theater”?
Agile Theater happens when a company adopts the terminology of Agile (Sprints, Standups, Scrum Masters) but fundamentally operates using rigid, top-down Waterfall methodologies. They hold the meetings, but lack the actual flexibility to iterate based on user feedback.
What does “Shift-Left” mean in software development?
Shift-Left is the practice of moving testing, security, and quality assurance to the earliest possible stages of the software development lifecycle (the “left” side of the project timeline), rather than waiting until the code is completely finished to find bugs.
Why is manual deployment considered dangerous?
Manual deployments require developers to directly access production servers. This introduces the risk of human error (e.g., uploading the wrong configuration file, skipping a database migration) and makes it incredibly difficult to rollback if the system crashes. Automated CI/CD prevents this.
What is a “Definition of Ready” (DoR)?
The DoR is an agreement between the product team and the developers. It states that a task cannot enter a development Sprint until it meets specific criteria: precise acceptance tests are written, the UI designs are final, and the API endpoints are agreed upon. This prevents developers from being blocked mid-sprint.
How does GitOps (like ArgoCD) improve the development process?
GitOps ensures that your Git repository is the single source of truth for your infrastructure. If the live server configuration deviates from what is written in the Git code, ArgoCD automatically detects the drift and forces the server back to the correct state, ensuring absolute consistency.
What is a “Blameless Postmortem” and why does it matter?
A blameless postmortem is a structured review conducted after a production incident that focuses exclusively on the systemic and process failures that allowed the incident to occur, rather than which individual made a mistake. This encourages engineers to report issues honestly and quickly, which is the only way an organization can permanently harden its processes against recurring failures.
What are the DORA “Four Keys” metrics, and how do they define an elite engineering team?
The Four Keys — Deployment Frequency, Lead Time for Changes, Change Failure Rate, and Time to Restore Service — are the research-backed metrics from Google Cloud’s DORA (DevOps Research and Assessment) program used to classify engineering organizations into Elite, High, Medium, and Low performance clusters. Elite teams deploy on demand with a lead time under a day, a change failure rate around 5%, and recover from incidents in under an hour, while low performers can take months to ship a single change. The key insight is that these metrics are balanced together: an elite team is fast and stable at the same time, not one at the expense of the other.
Suggested Posts
How useful was this post?
Share it with your friends


Get our latest articles here!
Thank you for subscribing to our blog!
Do you have any questions?
Help us improve the content of this Insightful blog by asking us questions. Manifera's team of experts will help you answer these questions as soon as possible.